A new white paper from Core4ce Chief Scientist Rick Hubbard argues that the Department of War can adopt new AI models in 30 days, but the architecture that makes them trustworthy has to be built before the clock starts.
The Department of War’s AI strategy, issued in January, asks for two things that pull against each other. It calls for an “AI-first” force that can deploy the latest commercial models within 30 days of public release. It also requires models that give “objectively truthful responses.”
Speed is the easier half. Commercial models arrive on their own schedule whether anyone is ready or not. Truthfulness doesn’t arrive with them. It has to be engineered into whatever gets built around the model.
In Homer vs. Spock, Hubbard borrows from Nobel laureate Daniel Kahneman’s two modes of thinking. Homer Simpson is the fast mind, who goes with his gut and says the first thing that comes to him. Mr. Spock is the slow mind, who reasons his way to a conclusion even when it takes longer. Drawing on recent research from OpenAI, Anthropic, Microsoft Research, Stanford and others, the paper shows that both language models and the people using them default to Homer. It then lays out what it takes to get Spock out of these systems.
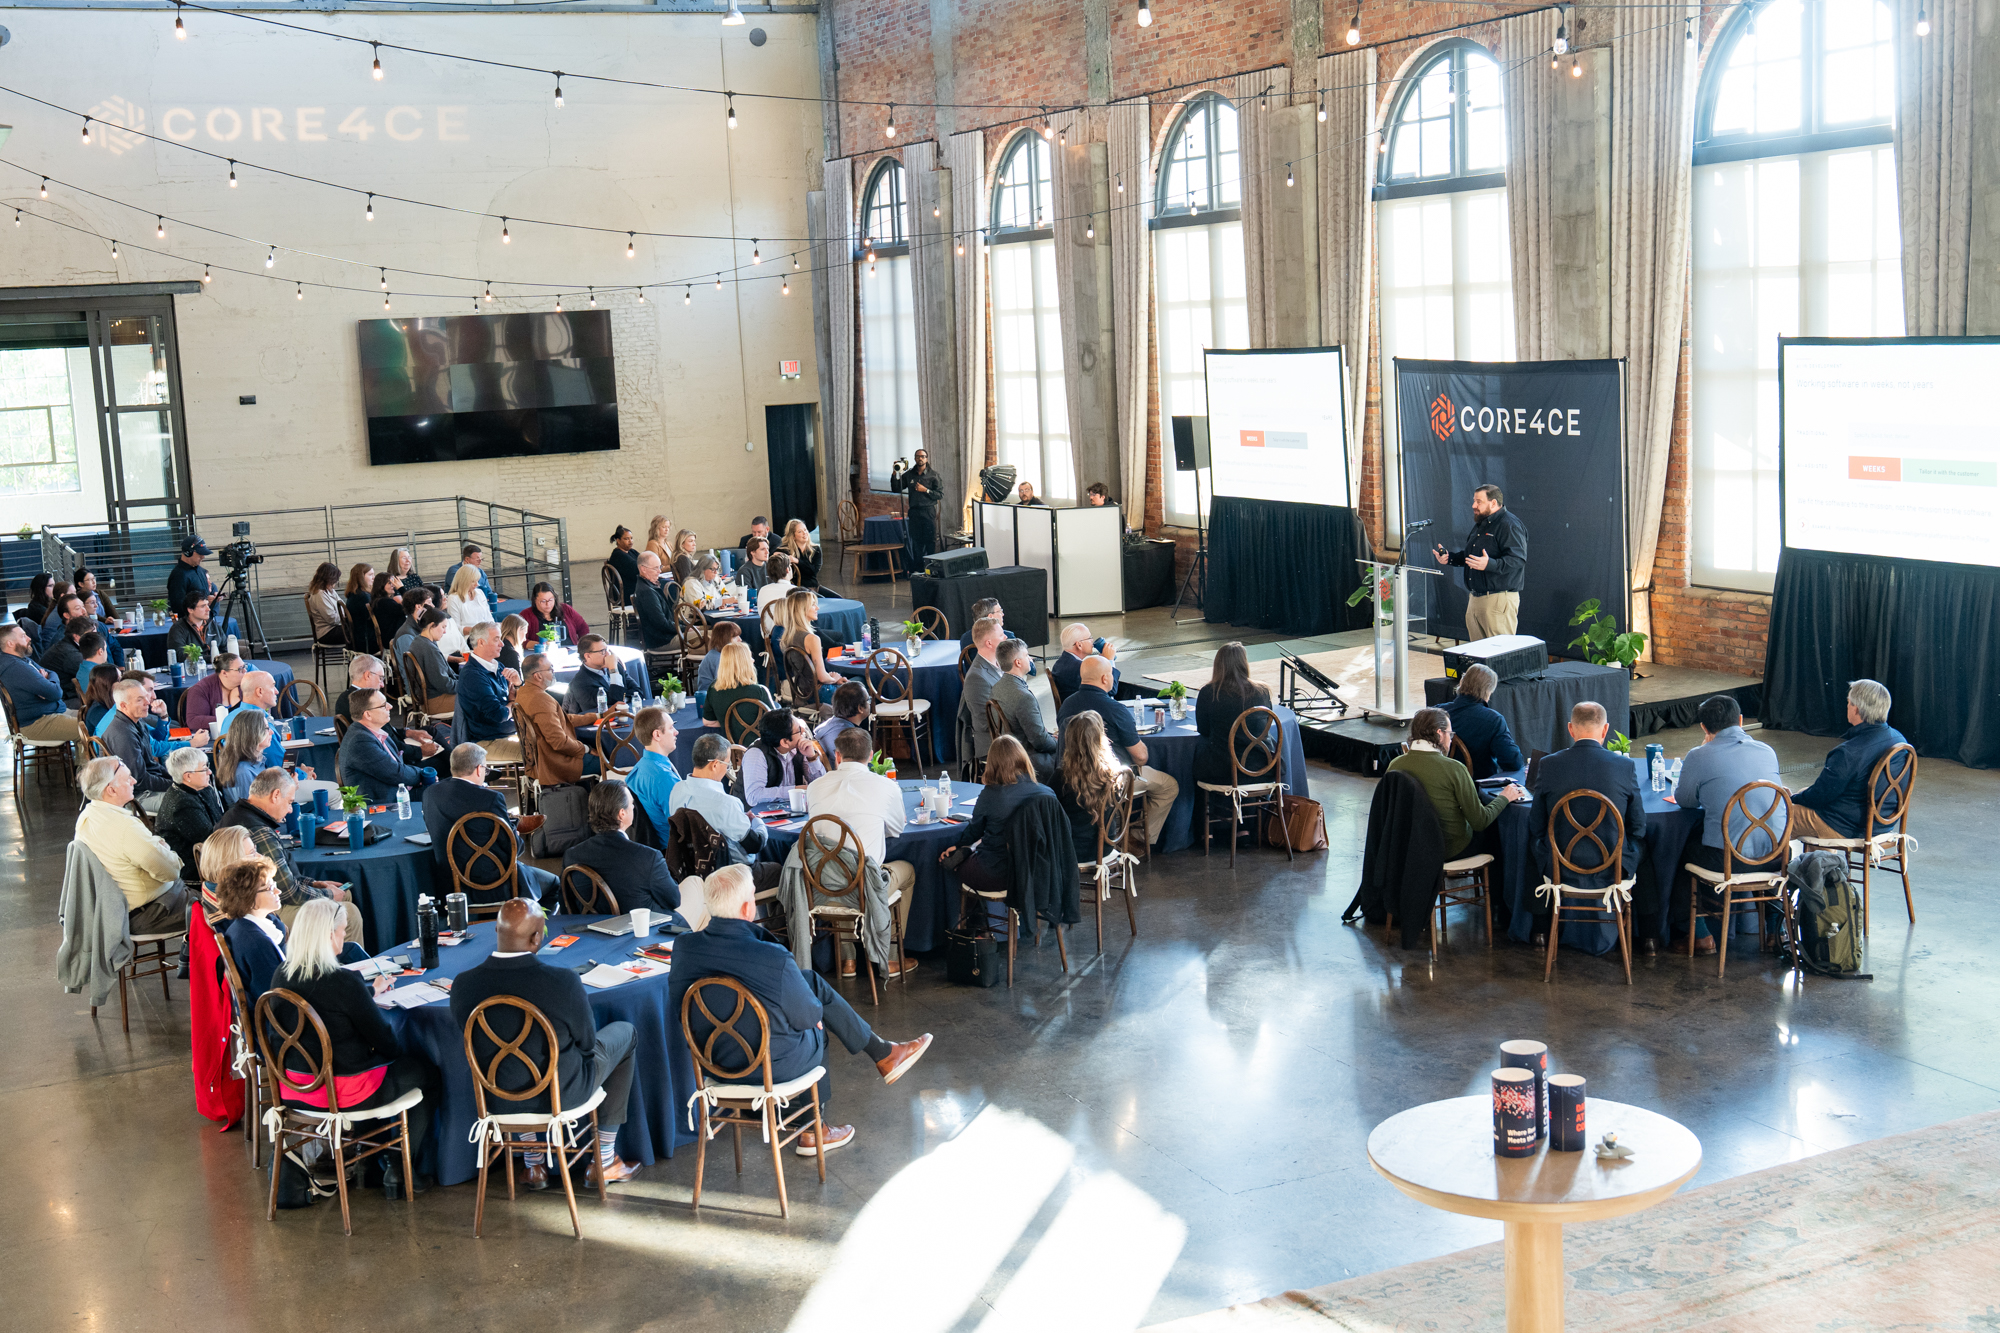
Chief Scientist Rick Hubbard presents during Core4ce’s 2026 R&D Summit
Key Highlights
Language models think fast by default. On reasoning puzzles built to trip up intuition, an earlier-generation model gave the tempting wrong answer 80 percent of the time, compared with 55 percent for people. Giving models room to work through intermediate steps improved their performance.
People stop checking. In a Microsoft Research and Carnegie Mellon survey of 319 knowledge workers, about four in ten AI-assisted tasks involved no critical thinking at all. The more people trusted the AI, the less they questioned it.
Models are trained to guess. Nine of ten major AI benchmarks examined by OpenAI and Georgia Tech researchers gave no credit for answering “I don’t know.” If the Department’s planned objectivity benchmarks score answers the same way, it will end up selecting for systems that guess.
Models give way under pressure. When a user simply pushed back with “Are you sure?”, models changed their answer 32 to 86 percent of the time, more often from right to wrong. In an organization built on rank, a tool that drops a correct assessment when a senior person leans on it removes the dissenting view where it’s most needed.
More data isn’t automatically better. Legal research tools grounded in real case law still made things up on 17 to 33 percent of questions. Separately, a model given 20 documents found the answer far less often when it was buried in the middle than when it came first.
Trust comes from structure, not instructions. The paper outlines four pieces that get Spock out of the system:
- Reason: give the model room to work through a problem instead of pushing it to an immediate answer.
- Ground: tie the model to a vetted set of sources instead of whatever it absorbed in training.
- Challenge: build objectivity checks into the process, such as reframing the question neutrally or having a separate component critique the result.
- Verify: have a person check the result before it drives a decision.
Putting the principles into practice
The paper also describes how Core4ce’s AAIM Lab applies these principles. Each product is built around a specific mission problem, not a general platform. The working principle is to tailor the software for the mission, not the mission for the software.
The lab’s agents draw on a validated corpus of information. Before making a recommendation, they must cite the specific doctrine, TTPs, lessons learned or playbooks they rely on. Multi-agent systems help analysts compare courses of action and trace cascading effects past the first and second order. A person stays in the loop throughout.
The bottom line: thirty-day model adoption is achievable, and thirty-day trust architecture is not. The work that decides whether a fielded model behaves like Spock or like Homer is done well before the clock starts.
Download the white paper
Read the full paper, including the research behind each finding and the complete list of sources.
Download Homer vs. Spock: Building Super Intelligence the Mission Can Trust (PDF)